
The frontier in coding agents is shifting from “which assistant writes the best patch?” to “how do we route work, approve risk, and keep a durable record when several agents can act on the same repository?” That change is visible in two directions at once: local agents are being exposed through remote messaging interfaces, while vendors add the less glamorous controls needed to make autonomous work tolerable inside a real engineering organization.
A GitHub project called cc-connect is a useful, early example. It connects local coding agents—including Claude Code, Codex, Cursor Agent, Gemini CLI, Copilot, Kimi CLI, and ACP-compatible clients—to platforms such as Slack, Telegram, Discord, Lark, and WeChat Work. Several of its platform paths use outbound connections rather than requiring a public IP address.[1] The project is not a reason to expose your laptop to every chat app. It is evidence that the interface around the agent is becoming as important as the editor hosting it.
The IDE is no longer the only place work starts
For years, the practical split was simple: autocomplete lived in an editor, while more capable agents lived in a terminal. That distinction still helps set expectations. AI coding assistants typically augment an existing IDE, while AI-native editors such as Cursor and Windsurf make the editor itself the persistent agent workspace; terminal-first tools such as Claude Code and Codex have also expanded into IDE, desktop, web, and background-task surfaces.[4]
But a task now often begins somewhere else: a production alert, a support conversation, a ticket comment, or a message sent during a commute. A chat interface can turn that signal into a structured request, ask an agent to inspect the relevant code, and return a plan or patch link to a human reviewer. The important distinction is not whether chat is convenient. It is whether the chat layer preserves identity, repository scope, approvals, and an audit trail.
This is why “remote agent” should not mean “unattended shell with a friendly UI.” A message saying “fix the checkout outage” has none of the constraints a competent developer would ordinarily gather: which environment, what rollback boundary, which tests, whether dependencies may change, and who can authorize a deploy. The control plane has to add those missing constraints before the agent starts executing.
ACP is the interoperability layer worth watching
The Agent Client Protocol (ACP) is emerging as a useful seam between a client or workspace and the agents it can run. The ACP topic on GitHub already includes projects built around running Claude, Codex, OpenCode, Gemini, Cursor, Copilot, and other agents side by side, as well as browser workspaces that show conversations, tool activity, and file changes.[5] cc-connect likewise advertises support for any ACP-compatible agent, alongside direct integrations.[1]
That matters because teams should avoid embedding their workflow rules in one vendor’s chat wrapper or IDE extension. A stable protocol boundary lets you swap the executor while retaining the pieces that ought to be yours: task schemas, repository instructions, approval rules, evaluation fixtures, logs, and notification channels. ACP does not magically standardize model quality or security, but it can reduce the coupling between the control surface and the agent underneath it.
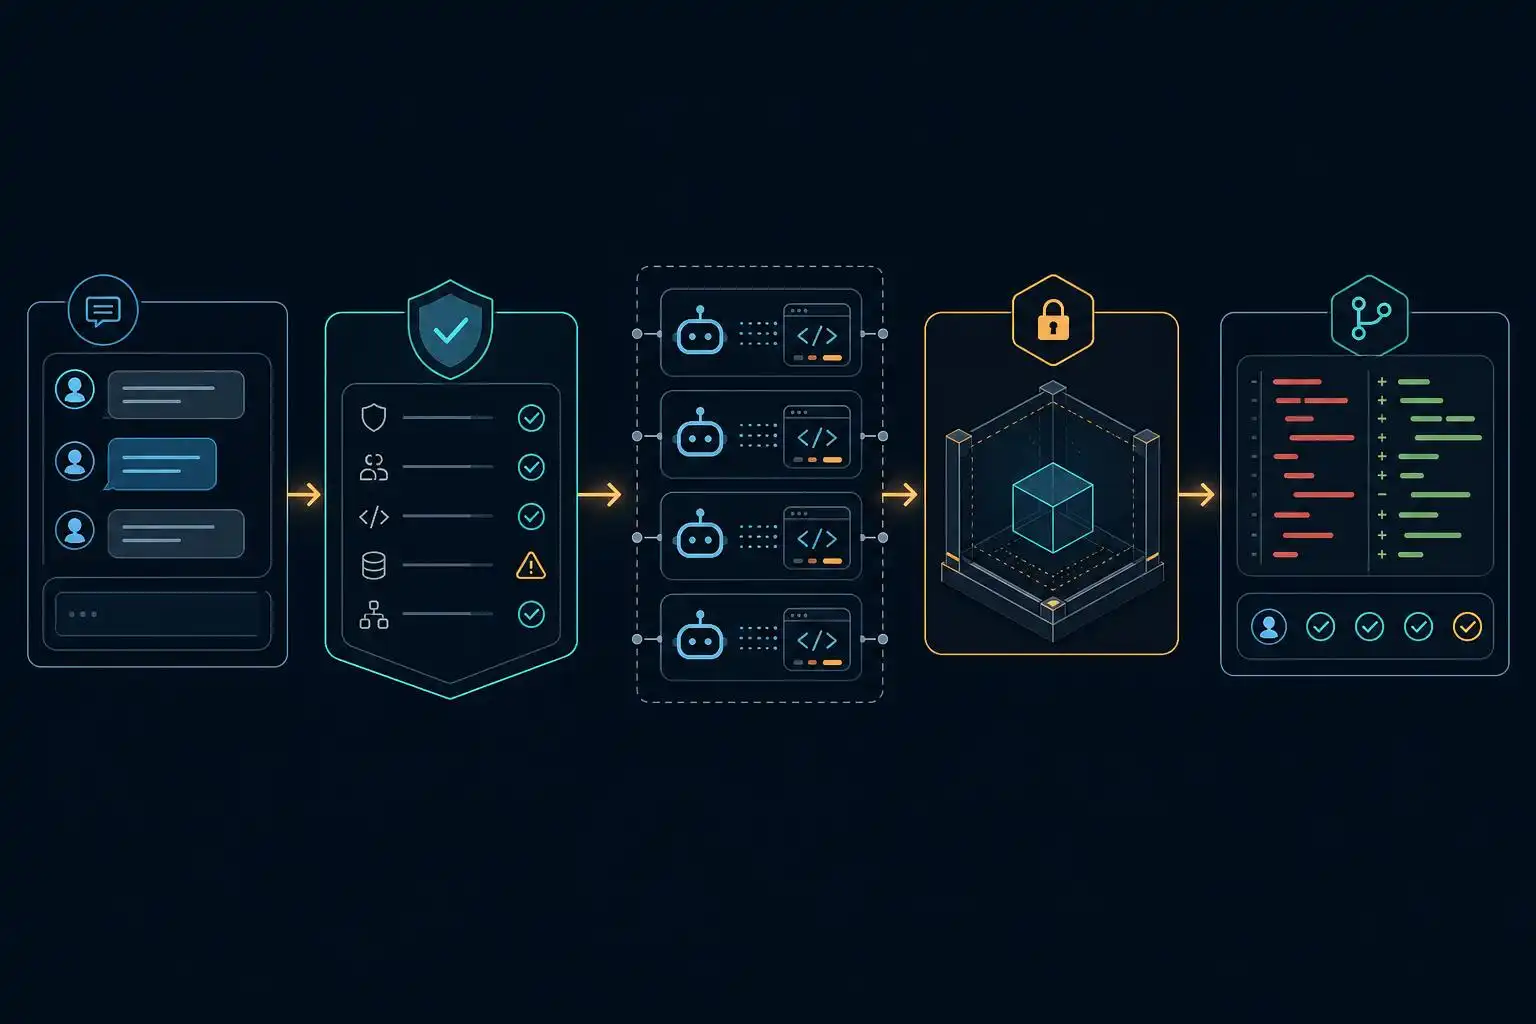
A reasonable architecture is deliberately boring:
Slack/Jira/incident event
        │
        ▼
Task gateway ── policy + identity + repository allowlist
        │
        ▼
ACP/direct adapter ── selected coding agent
        │
        ▼
Ephemeral worktree or sandbox ── tests, diff, artifacts
        │
        ▼
Pull request + human approval + CI deployment controls
The gateway is the critical component. It should validate the request, select an allowed agent and execution environment, issue narrowly scoped credentials, and report results through existing engineering systems. Treating a messaging bot as the gateway itself is a shortcut that becomes painful the first time you need to answer who approved a destructive command.
Governance is finally becoming a product feature
The near-term agent race will not be won solely by benchmark scores. Recent Claude Code releases point toward operational controls: a maxEffortLevel setting for limiting reasoning effort, cost visibility, output-style controls, and claude plugin eval for reproducible scored plugin evaluations. A contemporaneous roundup also reports Copilot moving toward adaptive routing across models and adding Jira integration.[2]
These are easy features to dismiss as enterprise plumbing. They are actually prerequisites for delegation. If an agent can autonomously investigate a flaky test, the team needs a predictable effort budget. If it can load plugins or invoke tools, the team needs a way to evaluate changes to those extensions before broad rollout. If a platform chooses among models, teams need visibility into which model ran, why it was selected, what it cost, and whether its permissions differed.
The policy question is therefore more precise than “can agents use tools?” It is: which agent may use which tools, on which repository, with what data, for how long, and with which human checkpoint? Good defaults differ sharply between a documentation cleanup and a payment-service incident.
Build a small task contract before adding remote access
Start by requiring a structured task contract, whether work originates in chat, Jira, or a CLI. The contract gives the agent enough direction to act without turning a vague request into an open-ended exploration. It also gives reviewers a clear basis for accepting or rejecting a result.
# .agent/tasks/fix-flaky-checkout-test.yaml
repo: acme/storefront
branch: agent/fix-checkout-test
objective: Stabilize the intermittently failing checkout integration test.
allowed_paths:
  - tests/integration/checkout/**
  - src/checkout/**
commands:
  allow:
    - "pnpm test:integration -- checkout"
    - "pnpm lint"
    - "git diff --check"
  deny:
    - "git push --force"
    - "kubectl *"
    - "terraform apply*"
limits:
  max_runtime_minutes: 20
  max_agent_turns: 30
  max_cost_usd: 8
required_output:
  - diagnosis.md
  - test-results.txt
  - pull-request
approval_required_for:
  - dependency_changes
  - database_migrations
  - ci_configuration_changes
This is not security theater. The path allowlist prevents a test fix from quietly rewriting deployment configuration; command restrictions block the most obvious escalation paths; budgets turn a runaway investigation into a bounded failure. Keep the contract beside code where it can be reviewed, versioned, and refined after incidents.
For message-triggered workflows, make the initial action read-only by default. Let the agent summarize the suspected files, propose a plan, and estimate the scope; then require an explicit approval token before it edits, opens a pull request, or calls any privileged integration. A short conversation can remain convenient without becoming an implicit production authorization.
Separate investigation, implementation, and release
A reliable multi-agent workflow does not ask every model to do everything. Use a lower-risk investigator to map the code path and gather evidence, an implementation agent in an isolated worktree to make a small patch, and deterministic CI plus a human reviewer to decide whether it merges. Different tools can serve those roles; the common task contract and artifact format matter more than a single-vendor stack.
When using an adapter such as cc-connect, keep the machine hosting the local agent in the same threat category as a developer workstation or a build runner, not as a harmless chatbot. Use a dedicated OS account, a separate checkout, short-lived tokens, a repository allowlist, and restricted network egress where practical. Never let a chat command inherit your full interactive cloud credentials merely because it is technically easier.
Also log more than the final diff. Preserve the original request, selected agent and model, instruction files used, tool calls, command output, changed files, test results, cost or effort metadata, and every approval. These artifacts make failures diagnosable and create the evaluation corpus you will need when changing models, prompts, plugins, or routing rules.
Choose the control plane before choosing the “best” agent
Social-media rankings can be a helpful discovery mechanism, but they flatten important differences into a single score. One recent developer-tools list rates Cursor, Claude Code, GitHub Copilot, Windsurf, and Codex highly while describing distinct strengths such as AI-native IDE workflows, complex-codebase reasoning, and everyday pair programming.[3] Those are useful starting categories, not a procurement strategy.
Run a short pilot that measures the work your team actually delegates. Pick two or three repeatable task classes—test repair, dependency upgrade, bounded refactor—and score each run on patch acceptance, time to reviewable PR, test reliability, human interventions, cost, and policy violations. Include one intentionally constrained task to verify that the system refuses prohibited actions correctly.
The winning setup may contain multiple agents. What makes it manageable is a consistent operating model: one request format, isolated execution, observable outputs, explicit escalation, and CI as the merge gate. Chat and ACP can make that model available from more places; governance controls make it safe enough to use repeatedly.
Key takeaways
- Messaging bridges make local coding agents accessible anywhere, but they must sit behind identity, policy, and approval controls.
- ACP is promising because it can separate your workflow control plane from a particular agent vendor or IDE.
- Effort caps, cost reporting, plugin evaluation, and model-routing visibility are core delegation features, not optional enterprise extras.
- Start remote work read-only, use isolated worktrees and short-lived credentials, and require explicit approval before writes or privileged actions.
- Evaluate agents by task outcomes and policy compliance—not a single leaderboard score.
References
- GitHub – chenhg5/cc-connect: Bridge local AI coding agents (Claude …) — https://github.com/chenhg5/cc-connect
- AI Tools Weekly: Claude Code’s New Governance Controls + 4 More Updates — https://www.joinnextdev.com/blog/ai-tools-weekly-claude-codes-new-governance-controls-4-more-updates
- Developers in 2026 aren’t just writing code they’re building with AI … — https://www.instagram.com/p/DdCA17bmon8
- 7 Best AI Coding Tools for Complex Codebases — https://www.greptile.com/content-library/ai-coding-tools
- agent-client-protocol · GitHub Topics — https://github.com/topics/agent-client-protocol?o=desc&s=updated

Leave a Reply