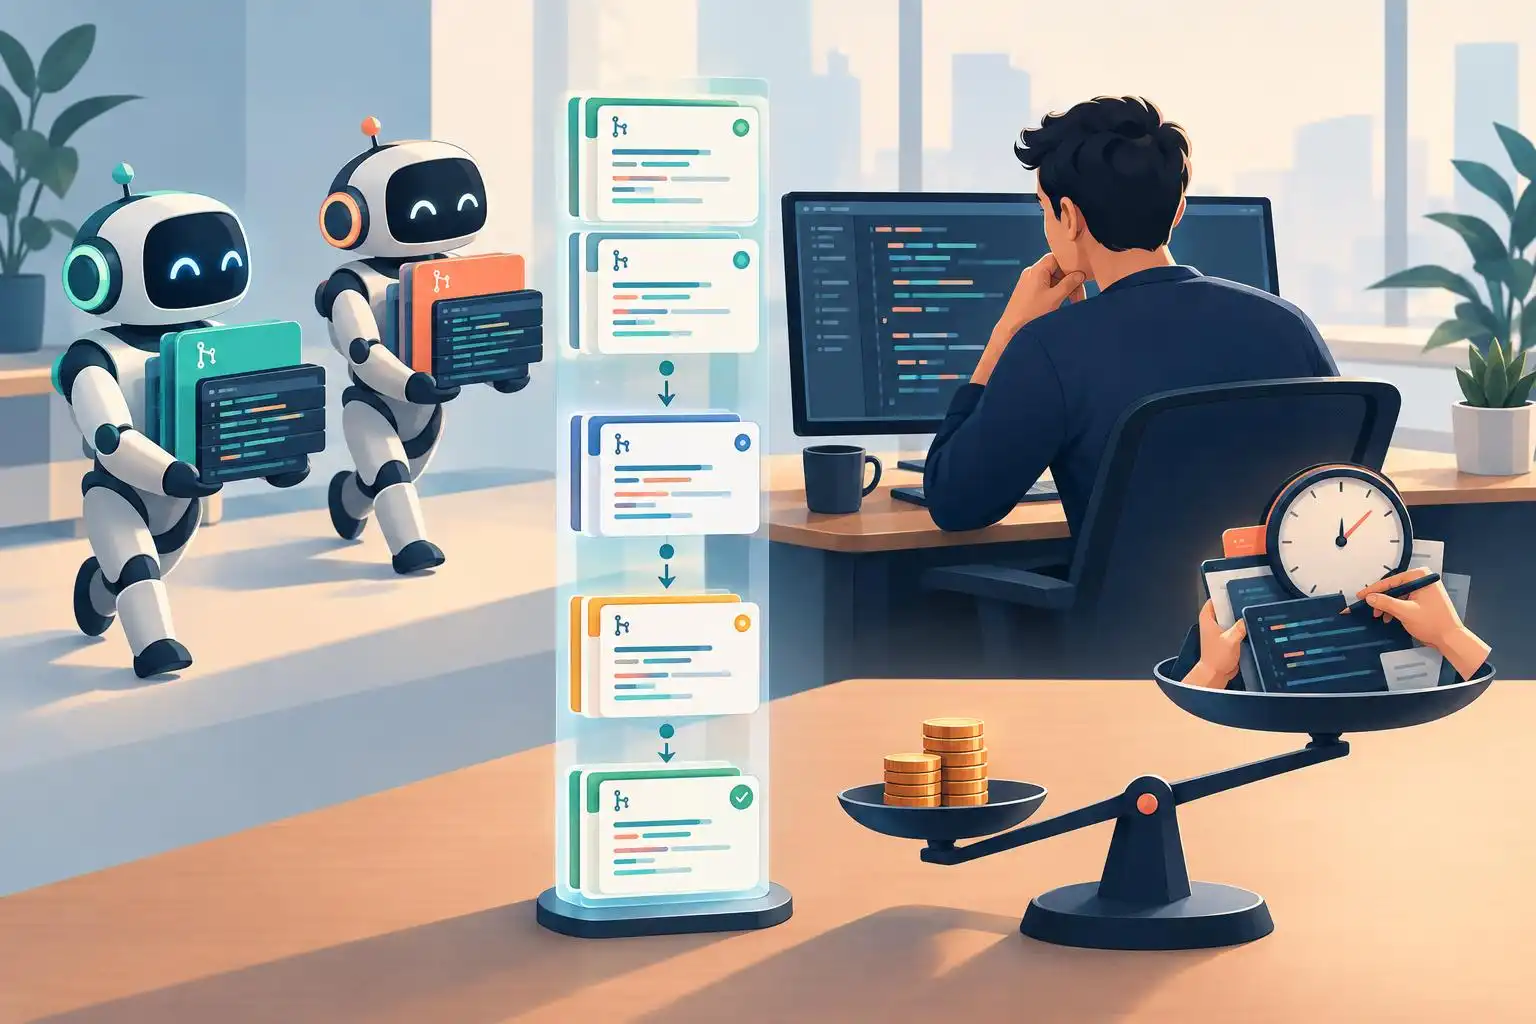

A coding agent that costs less per seat can still be the expensive choice. Give two agents the same issue and one may finish faster, while the other consumes more review time, leaves a flaky test, or produces a patch nobody wants to merge. The invoice captures only part of that difference.
Recent comparisons agree that Claude Code, Codex, Cursor, and GitHub Copilot can do more than autocomplete: they can edit across files and run multi-step coding tasks. They also point to different working styles, from editor-based interaction to terminal and asynchronous cloud work.[1][2] That makes a price-per-seat table a poor way to decide which agent gets your next repository task.
Start with the task, not the subscription
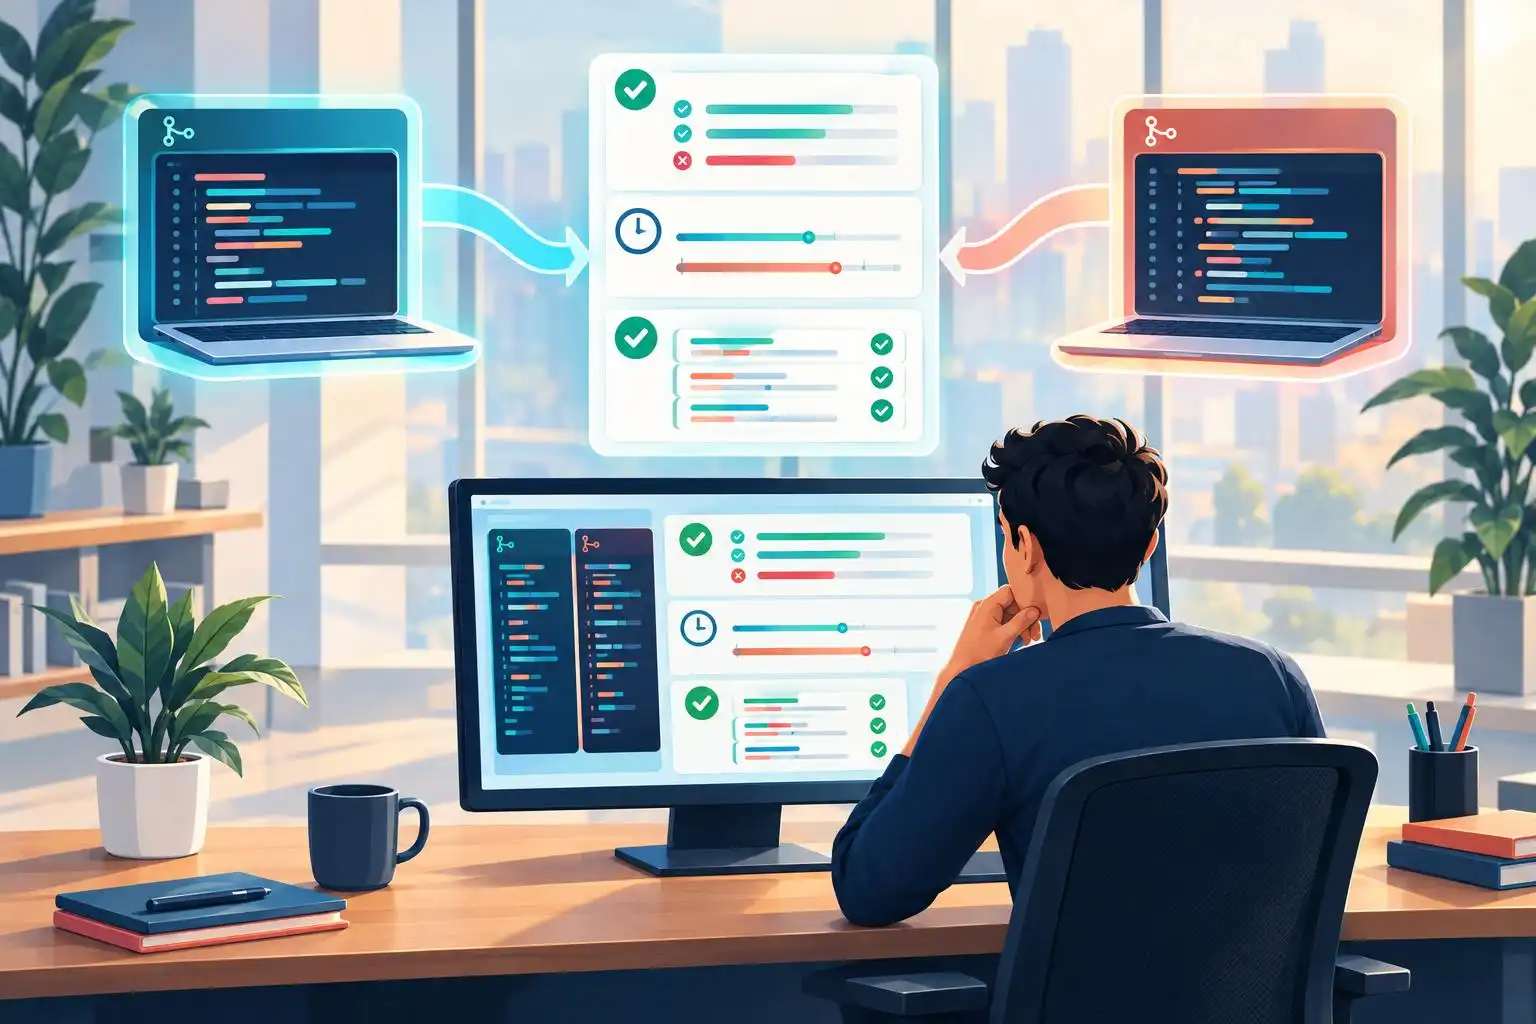
Define one representative task before comparing plans. A useful candidate has a clear acceptance test, requires a change in more than one file, and resembles work your team would actually delegate. A tiny autocomplete exercise favors editor tools; an overnight pull-request assignment favors background agents. Neither tells you much about the other workflow.
Write down the starting commit, task prompt, allowed commands, and definition of done. Give each tool its own clean worktree so one attempt cannot benefit from another’s edits. For a repository with a Python test suite, the setup might look like this:
git fetch origin
git worktree add ../agent-cursor origin/main
git worktree add ../agent-codex origin/main

# Run the same baseline check in each worktree before starting.
(cd ../agent-cursor && python -m pytest -q)
(cd ../agent-codex && python -m pytest -q)
Replace the test command with your project’s real check. Record the base commit hash, too: origin/main can move between attempts. Run agents sequentially if they share rate limits or infrastructure that could skew timing.
Count the review queue as part of the cost
For each attempt, measure more than whether the agent declared success. Keep the record small enough that an engineer will fill it in:
- Outcome: Did the patch pass the stated acceptance checks and earn a merge recommendation?
- Human time: How many minutes went to prompting, supervising, reviewing, and repairing it?
- Machine spend: What did the provider report for requests, credits, tokens, or agent compute?
- Elapsed time: When was a reviewable patch ready, including waits and retries?
- Cleanup: Did the agent leave unrelated edits, missing tests, or a change that needed substantial rewriting?
Do not collapse those observations into a single score too early. A background task that takes an hour but needs five minutes of review may be better for one team than a ten-minute interactive session requiring an engineer’s full attention. Conversely, an agent that opens many plausible pull requests can overwhelm a team whose reviewers are already the bottleneck.
The growing directory of parallel runners and orchestration tools makes this distinction more urgent: launching several CLI agents is easier than establishing who will validate and merge their output.[4] More concurrent work is useful only when the review capacity exists to absorb it.
Put an uncertainty label on every pricing claim
Pricing summaries published close together can disagree on basic billing boundaries. One October 2026 comparison describes Claude Code access through Claude subscriptions and Codex availability across ChatGPT plans.[2] A September pricing roundup instead characterizes Claude Code as API-key usage-based only, while also discussing Claude Max, and describes Codex CLI and cloud access separately.[5] Those descriptions are not a safe basis for a purchasing calculation without checking the current terms for the account and access path you will actually use.
Product names deserve the same scrutiny. One comparison groups Devin with the product formerly called Windsurf; another prices Devin and Windsurf in separate rows.[1][5] Before adding either row to a spreadsheet, confirm the exact product, plan, included usage, and billing entity with the vendor.
For a pilot, capture a dated screenshot or export from each account’s billing page and note whether the agent ran under a subscription, organizational seat, API key, or cloud-task allowance. Treat third-party price tables as leads to investigate, not contractual terms. Report cost per accepted task alongside the bill: failed and abandoned attempts consumed resources even when they produced no mergeable code.
Choose the workflow that fits the handoff
The comparisons offer useful hypotheses. Cursor emphasizes an editor-centered experience with cloud-agent options; Claude Code appeals to terminal workflows; Codex supports delegated sandbox tasks; Copilot fits teams working within GitHub.[1] Test those claims at the handoff point that matters to you, rather than assuming one tool must win every task.
For an interactive bug fix, observe how readily a developer can inspect intermediate edits and redirect the agent. For an asynchronous assignment, inspect the final diff, test evidence, and explanation without relying on the agent’s own success summary. Apply the same permissions and review rules to every candidate; otherwise you are comparing operating policies as much as tools.
The result should be a routing rule, not a universal leaderboard: which tasks belong in the editor, which can wait in a background queue, and which still need a human to drive. Revisit that rule when plans or capabilities change. The durable measurement is not the advertised monthly price. It is the amount of trustworthy work your team can accept without moving the bottleneck somewhere worse.
Key takeaways
- Compare agents on identical repository tasks and clean starting commits.
- Measure review and repair time alongside provider-reported spend.
- Verify pricing against your actual account and access path; summaries can conflict.
- Route tasks by handoff style, not by a single overall winner.
References
- Best AI Agents for Coding: Code Smarter with Intelligent Helpers | Orchestra — https://www.getorchestra.io/knowledge-hub/comparisons/ai-coder-agent
- Best AI coding tools 2026: Claude Code vs Cursor vs Copilot · latentstack — https://mylateststack.vercel.app/blog/best-ai-coding-tools-2026
- awesome-cli-coding-agents | GitHub — https://github.com/bradagi/awesome-cli-coding-agents
- AI Coding Tools Pricing Compared (2026): Claude Code, Cursor, Copilot, Devin & More — amux — https://amux.io/blog/ai-coding-tools-pricing-2026

Leave a Reply
You must be logged in to post a comment.